Japanese speech starts talking sooner
Japanese synthesis now streams instead of waiting for the whole utterance. On CPU a 26-second sentence starts after 14.4 seconds instead of 25; on GPU it runs at RTF 0.069. The move also removes a hazard that could kill the entire perception process on JetPack 5.11.
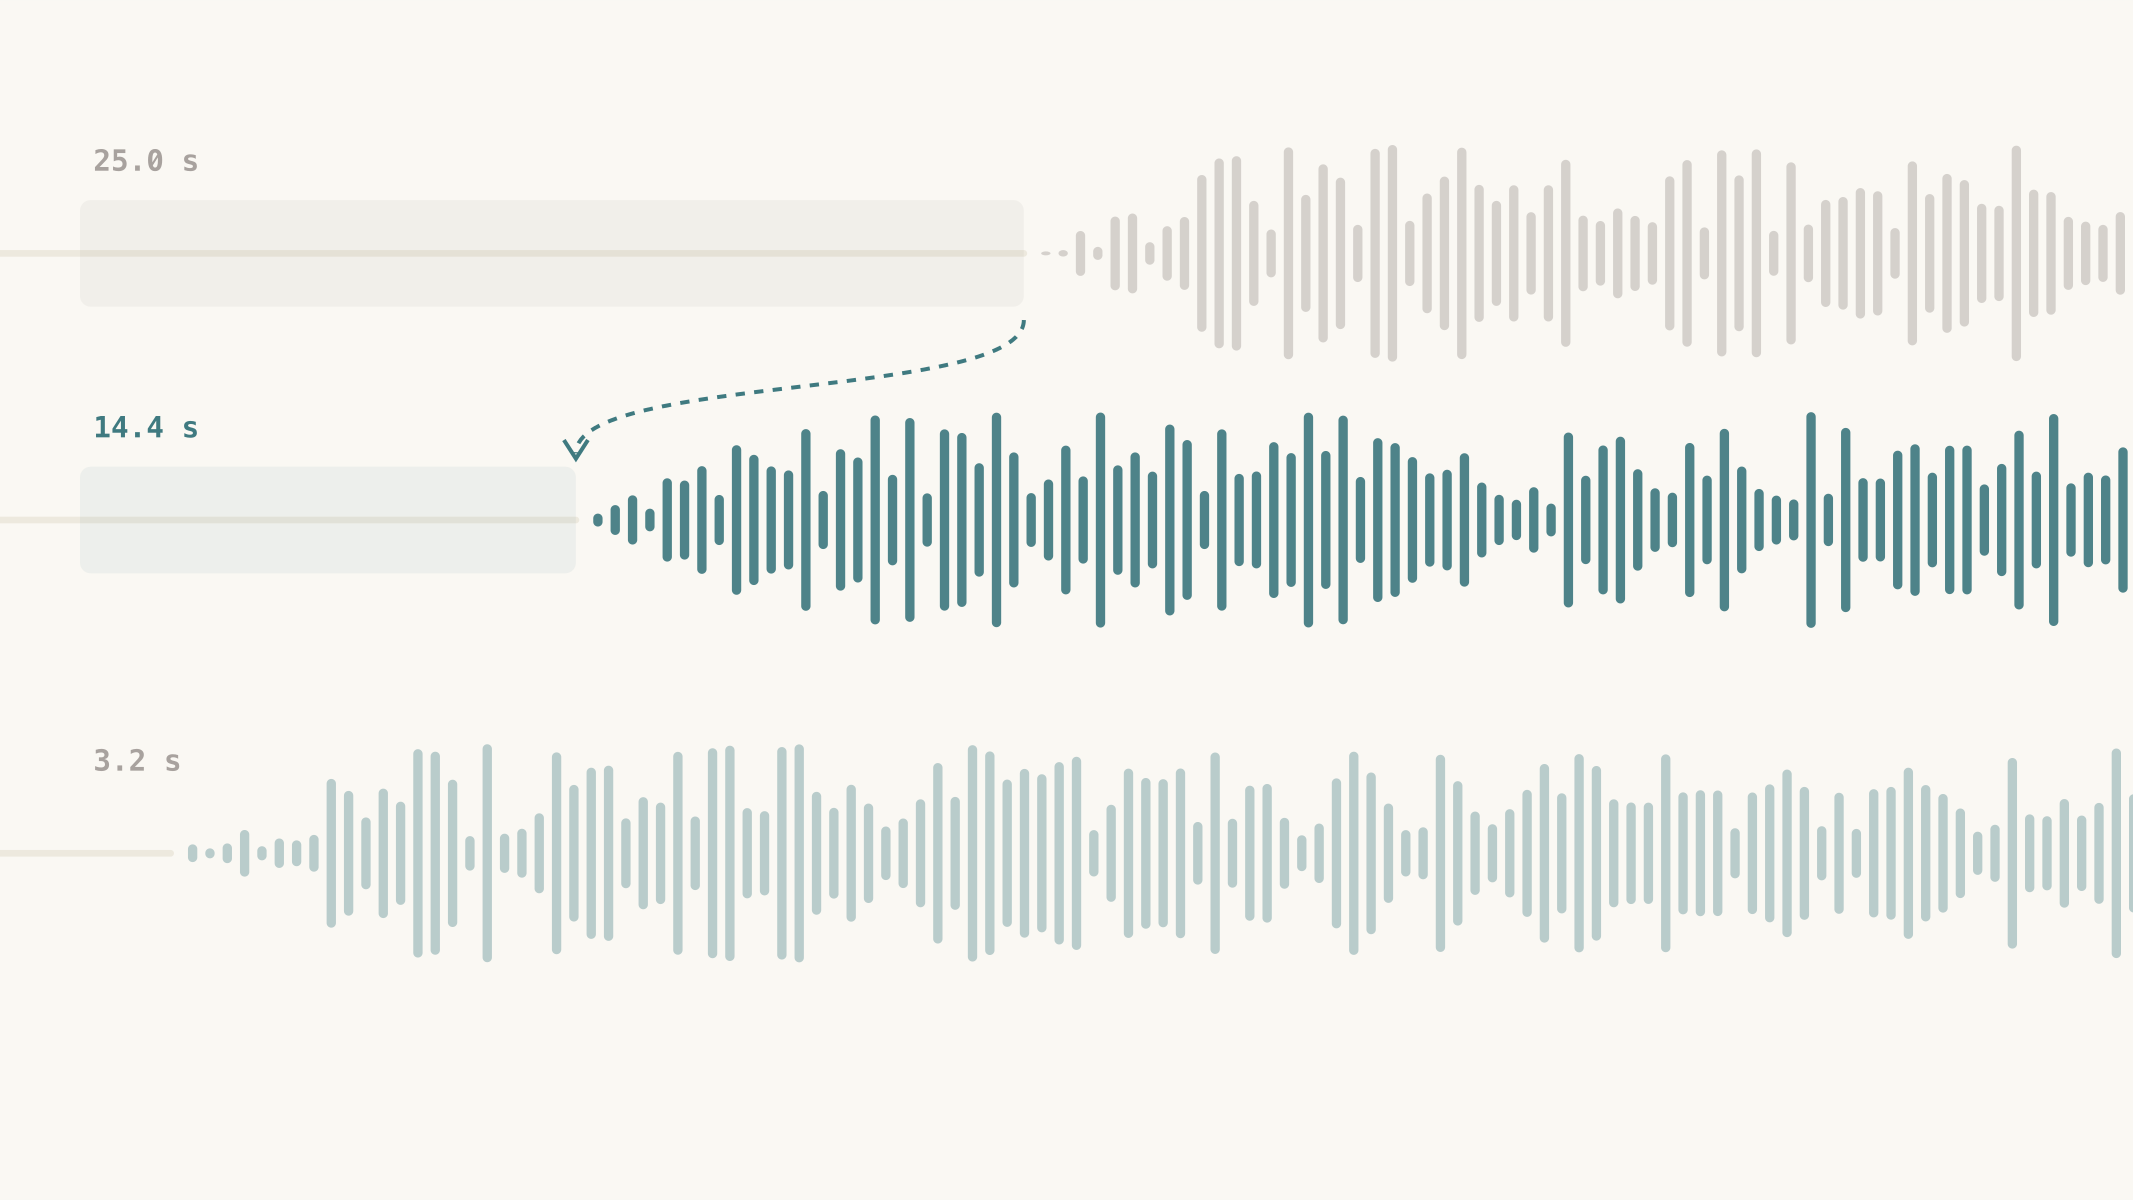
Japanese speech had an awkward habit: before a long sentence came out, the robot sat silent for a long time. It now speaks while it synthesizes.
A 26-second sentence starts more than twice as fast
| Silence before first sound | |
|---|---|
| Before (CPU) | ~25 s |
| Now (CPU) | 14.4 s |
| Now (GPU) | 3.2 s |
Synthesis used to wait for the whole utterance to finish computing before emitting any audio, rather than emitting as soon as there was enough to start playing. Long utterances are now split and streamed. Splitting too finely adds a little leading and trailing silence to each piece and sounds choppy, so the split point was tuned by measurement — and it only applies on CPU. On GPU synthesis is already fast enough that chunking would only cost padding.
On GPU the real-time factor is 0.069.
Also: a hazard that could take the whole robot deaf
The Japanese path and face recognition share a standalone inference runtime, and the perception process carries a second one. Two of them in one process corrupt each other. The symptom depended on the machine: on JetPack 6.1 the speech card errored out; on JetPack 5.11 the entire perception process died — taking speech recognition, object recognition and text recognition with it.
Those sessions now live in their own child process, so the two runtimes are never in the same address space. Nobody had hit this before only because reaching it required Japanese.